GPU Product
Rent NVIDIA L40S GPUs
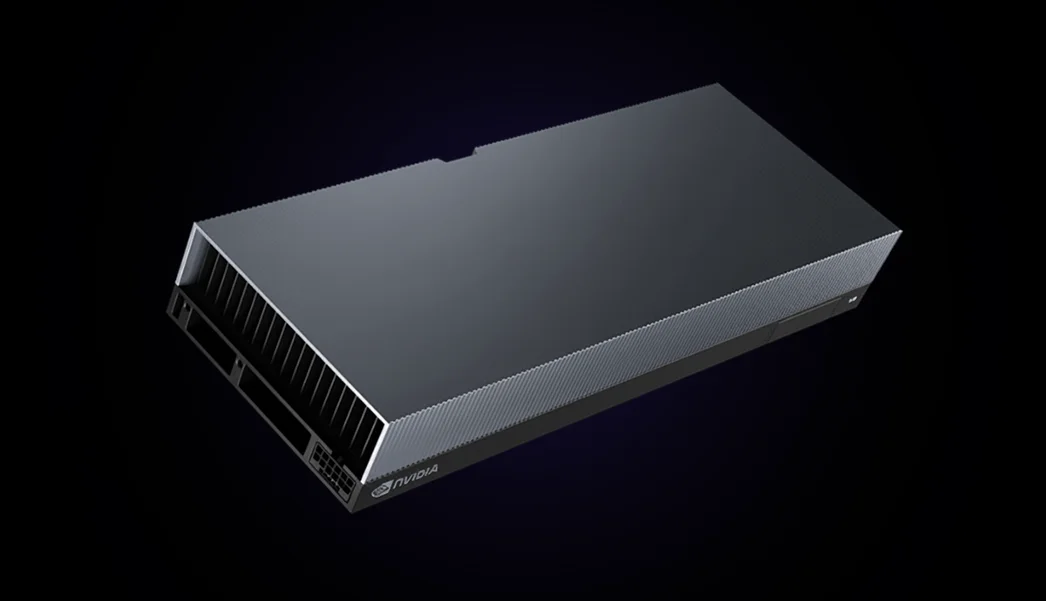
48 GB of GDDR6 memory with ECC, 733 TFLOPS of FP8 Tensor throughput, and full vGPU support in a passive, power-efficient 350 W dual-slot card. The Ada Lovelace architecture workhorse for AI inference, model training and fine-tuning, and virtual workstations.
Technical Specifications
L40S Rental Options
Rent NVIDIA L40S GPUs for production AI workloads, virtualized graphics, 3D design, and enterprise data center operations. On demand from $0.63 per GPU-hour, with reserved monthly terms available.
Comparison
L40S vs RTX 4090
| L40S | RTX 4090 | % Diff | |
|---|---|---|---|
| Architecture | Ada Lovelace | Ada Lovelace | N/A |
| CUDA Cores | 18 176 | 16 384 | +10.9% |
| Tensor Cores | 568 (4th gen) | 512 (4th gen) | +10.9% |
| RT Cores | 142 (3rd gen) | 128 (3rd gen) | +10.9% |
| Memory Type | GDDR6 ECC | GDDR6X | N/A |
| VRAM | 48 GB | 24 GB | +100% |
| Bus Width | 384-bit | 384-bit | 0% |
| Bandwidth | 864 GB/s | 1 010 GB/s | −14.5% |
| FP32 Performance | 91.6 TFLOPS | 82.6 TFLOPS | +10.9% |
| BF16/FP16 Tensor | 362 TFLOPS | 330 TFLOPS | +9.6% |
| FP8 Tensor | 733 TFLOPS | 661 TFLOPS | +11.0% |
| TDP | 350 W | 450 W | −22.2% |
| PCIe | PCIe 4.0 ×16 | PCIe 4.0 ×16 | N/A |
| Form Factor | Dual-slot | Triple-slot | N/A |
| Cooling | Passive | Active | N/A |
| Display Outputs | 4× DP 1.4a | 3× DP 1.4a | N/A |
| vGPU Support | Yes | No | N/A |
Performance
Key performance metrics
Enterprise AI Workloads
Built for AI inference and AI training: 18,176 CUDA cores at 91.6 TFLOPS FP32 and fourth-generation Tensor Cores for deep learning at production scale.
Virtualization Ready
Built for multi-tenant cloud environments: NVIDIA vGPU support for workstation virtualization and remote graphics, plus secure boot with a root of trust for enterprise data center operations.
Professional Graphics
142 third-generation RT Cores, 48GB ECC memory, and 3x NVENC/NVDEC with AV1 deliver real-time ray tracing performance for 8K video workflows, 3D design, and complex scene rendering.
Use Cases
What the L40S Is Good At
AI Inference
Deploy production AI models with high-throughput inference for real-time apps, and fine-tune them on the same power-efficient card.
Workstation VMs
Power remote design and engineering teams with GPU-accelerated graphics pipelines.
Rendering & VFX
Real-time ray tracing and high-resolution rendering for visual-effects production.
Multi-Tenancy
Serve multiple users with secure, isolated GPU resources at high concurrency.
The cloud GPU price comparison puts our L40S rate next to AWS, Azure, Google Cloud, RunPod and Lambda, per GPU-hour, dated and sourced.
NVIDIA L40S FAQ
Common Questions About the L40S
Ready to get started?
Get in touch with our team to discuss your requirements and find the right solution for your infrastructure.